How to Write Image Prompts: Layering, Visual Vocabulary, and Failure Fixes
Learn a reliable five-layer prompting structure, master practical photographic and artistic vocabulary, diagnose common generation failures, and organize an iterative testing workflow.
 ImageGenerator Team
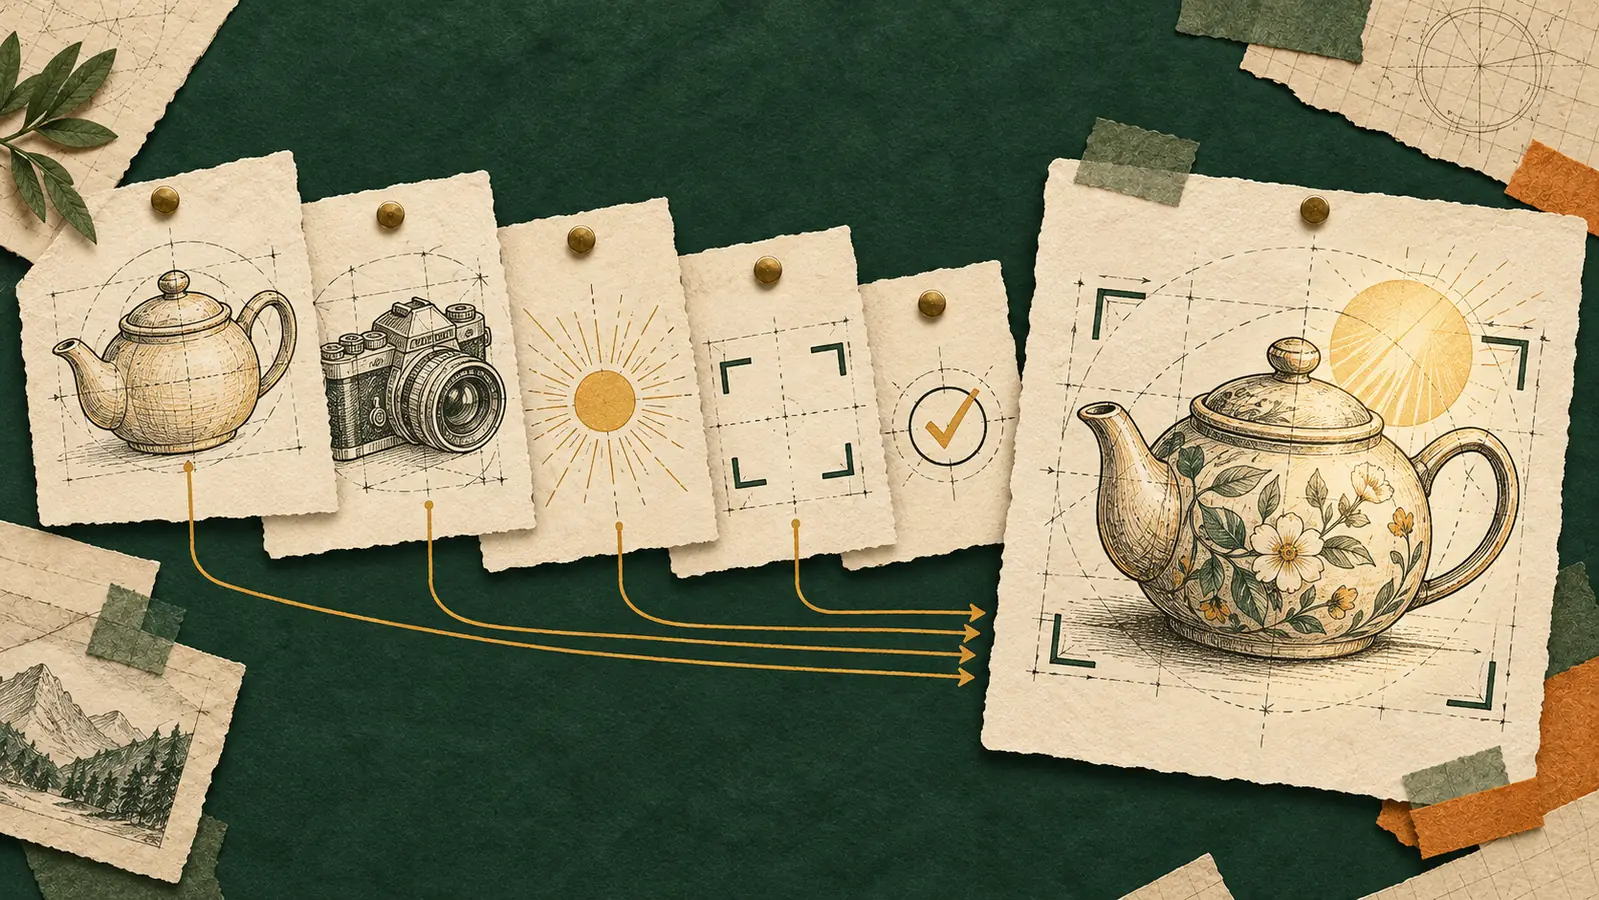
Disappointing visual generations often stem from prompts that leave too many essential creative decisions unspecified, though model capabilities and randomness also play a role. An instruction like "a studio product shot of a coffee cup" specifies the subject, but leaves lighting direction, camera distance, background texture, and color palette unstated. When those variables are omitted, unspecified details are left to the model to resolve, which can lead to generic or unexpected compositions.
On ImageGenerator.app, where creators can test prompts across a catalog of thirteen foundation vision models from a single unified input box, writing effective prompts is less like searching the web and more like drafting a concise creative brief for an art director or photographer. The solution to unpredictable images is not adding longer paragraphs of descriptive filler or pasting generic buzzwords like "photorealistic" or "hyper-detailed." Instead, reliable generation comes from stating the core visual layers clearly and in an order the model can parse effectively.
This guide presents a five-layer prompt structure that works consistently across models, breaks down practical photographic and medium vocabulary without confusing camera labels with mechanical lenses, provides three fully worked prompt evolutions, diagnoses five common generation failure modes with concrete fixes, provides audit checklists, and establishes an organized local testing workflow.
For guidance on comparing reference workflows and choosing foundation models, read our companion articles on Text to Image vs Image to Image and Choosing an AI Image Model.
The Five-Layer Prompt Architecture
When composing an image prompt, organizing your clauses in a predictable semantic order helps the model interpret your priorities. A reliable structural sequence moves from the central subject outward to the surrounding environment and visual treatment:
Subject → Medium & Treatment → Lighting → Framing & Perspective → Constraints & Checks
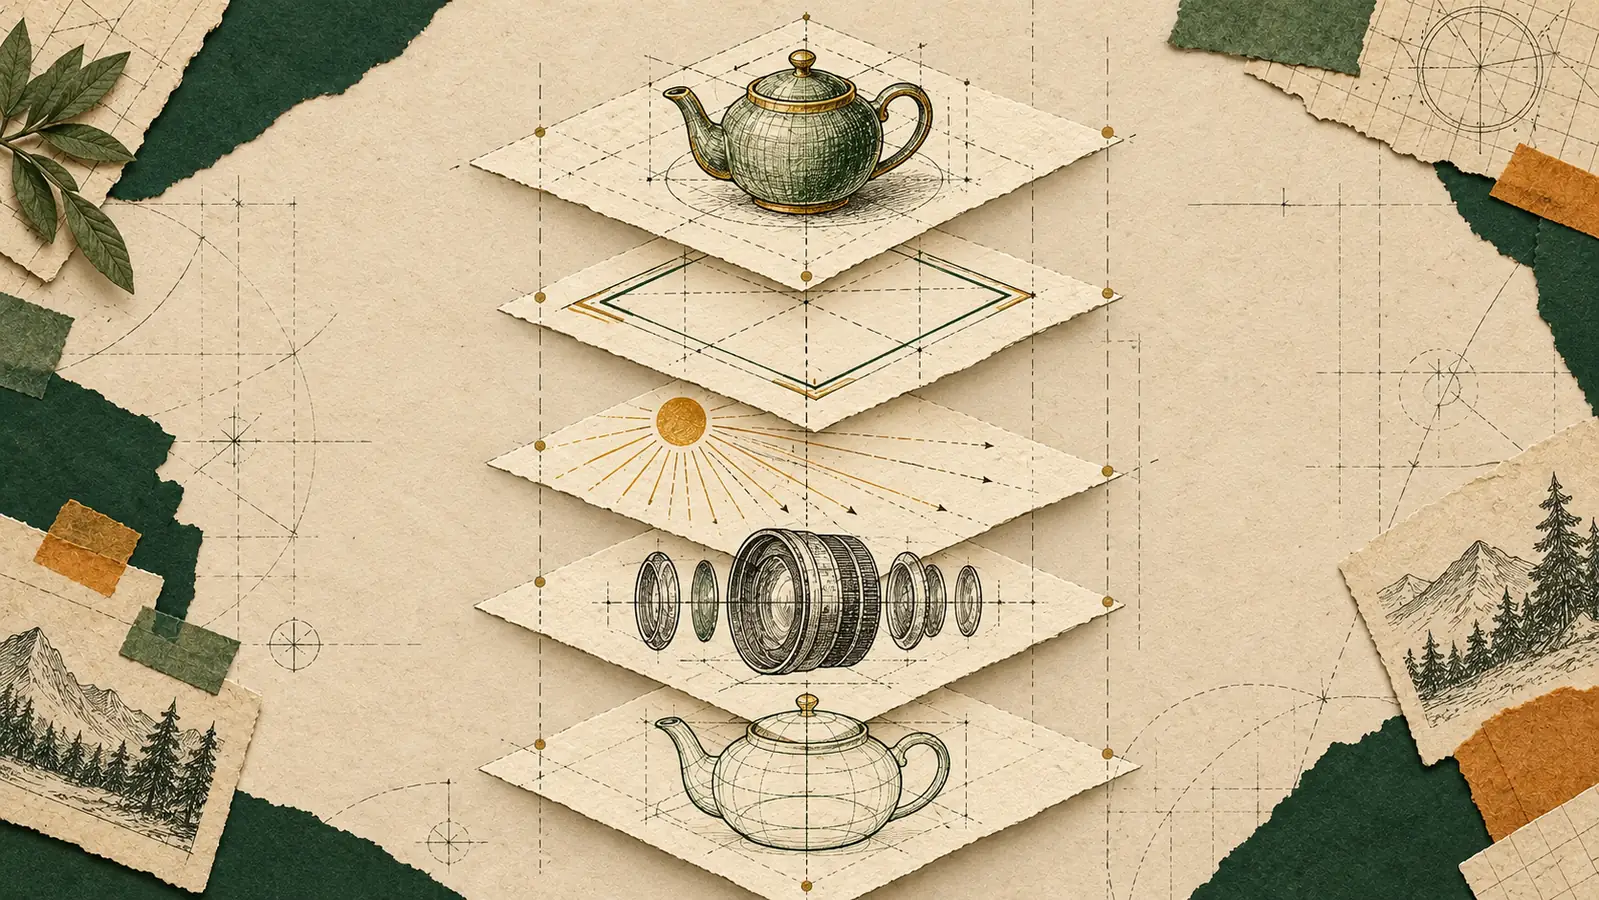
Layer 1: Core Subject Definition
The core subject is the primary anchor of the entire image. Be specific about the noun, material, and immediate state:
- Avoid vague nouns like "a person" or "a device."
- Use concrete descriptions: "a ceramic teapot with a looped handle," "an industrial designer sketching at a drafting table," or "a pair of matte black studio headphones."
- Include immediate physical characteristics such as material, surface finish, and color in the subject phrase itself.
Layer 2: Medium and Visual Treatment
The medium tells the model what kind of visual object it is creating. Without a defined medium, models default to an ambiguous blend of commercial digital render and stock photography.
- Explicit photographic styles: "editorial studio photograph," "35mm street documentary photograph," or "macro product photograph."
- Explicit illustration styles: "hand-printed linocut illustration," "flat vector graphic with clean outlines," or "editorial gouache painting."
- Architectural and design treatments: "architectural presentation rendering," "exploded axonometric drawing," or "minimalist Swiss graphic poster."
Layer 3: Illumination and Atmosphere
Lighting establishes the emotional tone, surface texture, and depth of the scene. Specifying lighting removes one of the largest sources of randomness in generation:
- Direction: Side lighting, soft directional window light, backlit rim lighting, or top-down overcast daylight.
- Quality: Diffuse, high-contrast, soft morning light, or harsh midday sun with sharp contact shadows.
- Color Temperature: Warm golden hour glow, cool twilight blue hour, or neutral balanced studio flash.
Layer 4: Framing, Distance, and Perspective
Framing dictates where the camera stands and how much of the scene is visible:
- Camera Distance: Extreme close-up on surface engraving, tight portrait crop from chest up, medium tabletop still life, or wide establishing environmental landscape.
- Angle of View: Eye-level straight-on view, low angle looking upward for monumental scale, top-down flat lay, or slight high-angle overview.
- Negative Space: Explicitly indicate if you need empty space around the subject: "generous negative space on the left for text layout" or "centred subject with ample margin around all edges."
Layer 5: Constraints and Verification Checks
Because the workspace interface does not include a separate negative-prompt input box, any visual boundaries or exclusions must be written directly into the main prompt container:
- Concise Exclusions: Concise negative constraints (such as "no text on the packaging" or "clean background without clutter") can be included in your prompt sentence.
- Positive Framing: Pairing negative constraints with positive descriptions (such as "a plain, unadorned concrete surface") often provides clearer guidance on what should occupy the frame. Test both approaches to see which gives better results for your specific subject.
- Define What to Inspect: Note specific quality checkpoints before generating: verify that on-image words are spelled correctly, object counts match your brief, and surface reflections align with your lighting description.
Visual Vocabulary: What Terms Actually Communicate
A frequent misconception in prompt engineering is assuming that models possess physical camera optics, real focal planes, or mechanical f-stop apertures. Modern AI image models do not have glass lenses, shutter blades, or optical sensors. When you write "85mm f/1.8," the model does not adjust a lens formula; it activates visual associations learned from millions of photographic captions paired with that metadata.
Understanding this distinction allows you to use photographic and artistic terminology effectively as stylistic shorthand without making false technical assumptions.
Visual vocabulary terms like "flat vector illustration" or "85mm f/1.8 portrait lens" guide the stylistic appearance and framing of the synthesized image. They do not generate true editable vector files (such as SVG paths) or simulate calibrated optical glass. Output is delivered as a raster image reflecting the requested artistic aesthetic.
Photographic Vocabulary as Semantic Shorthand
When you use camera descriptors, treat them as indicators of framing distance, perspective compression, and background separation:
- "85mm portrait lens": Signals a tight or medium portrait crop with minimal facial distortion, comfortable working distance, and gentle background blur that keeps attention focused on the person.
- "35mm documentary lens": Signals a wider environmental portrait where the subject interacts naturally with the surrounding room, street, or workspace, with moderate depth of field.
- "Macro photograph": Signals extreme close-up focus on fine surface textures, such as the knurling on an audio dial, the weave of linen fabric, or water droplets on glass.
- "f/2.8 shallow depth of field": Signals clear subject separation with soft, blurred background elements and sharp focus on the primary plane.
- "f/11 deep focus throughout": Signals crisp edge-to-edge sharpness across foreground, middle ground, and background, essential for architectural layouts and complex still lifes.
Art and Illustration Terminology
When your project requires illustration rather than photography, choosing precise traditional art terms prevents the model from generating cheap-looking synthetic gradients:
- "Linocut print with carved block texture": Produces bold graphic silhouettes, high contrast, and tactile ink impressions with subtle paper grain.
- "Editorial gouache illustration": Yields rich, opaque matte color planes with visible brush edges, popular in contemporary book and magazine publishing.
- "Technical pen and ink cross-hatching": Generates precise contour lines, textured shading, and architectural draftsmanship without photographic fills.
- "Risograph two-color print in vermilion and indigo": Emulates overlapping spot-color ink screens, slight misalignment, and tactile uncoated paper stock.
Graphic Design and Layout Terminology
For posters, banners, and editorial compositions where visual hierarchy is essential:
- "Swiss-style modular grid layout": Encourages strict alignment, rectangular division of space, structured margins, and deliberate typographical hierarchy.
- "Generous negative space": Commands the model to leave large areas of the canvas empty, providing breathing room for headlines, buttons, or product copy.
- "Flat lay tabletop arrangement": Directs the model to stage objects from an exact 90-degree overhead vantage point, neatly spaced and aligned.
Worked Prompt Evolutions: From Naive Idea to Polished Brief
To see how the five-layer structure transforms generation quality, examine three real-world creative briefs evolved step by step from naive one-liners into production-ready prompts.
Case Study 1: Ceramic Tableware Product Shot
- Creative Brief: A minimal product photograph of a ceramic coffee mug for an online homeware store catalog.
Evolution 1 (Naive Prompt):
A ceramic coffee mug on a table.
- Analysis: This prompt leaves color, surface glaze, lighting, and camera distance unspecified. The risk is that the model must decide these elements without guidance, which may result in an arbitrary centered object or mismatched background lighting.
Evolution 2 (Adding Layers 2 and 3):
Studio product photograph of a handmade cream ceramic coffee mug on a pale limestone tabletop, soft morning window daylight from the left, natural contact shadow.
- Analysis: The medium is now clearly photographic. The mug has an explicit material and color, the tabletop surface is specified, and the light has a defined direction and character. The image will look considerably more professional, but the framing and background separation remain undefined.
Evolution 3 (Full Five-Layer Production Prompt):
Editorial commercial product photograph of a handmade cylindrical coffee mug made of speckled cream ceramic with a wide loop handle, resting on a honed pale limestone surface. Soft morning side daylight entering from the left, creating gentle highlights on the ceramic rim and a soft, realistic contact shadow on the stone. Medium-close framing at a thirty-degree angle, sharp focus across the mug body, neutral warm-grey studio background with generous negative space at the top.
- What to Inspect in the Output: Verify that the mug handle is clean and properly joined to the body, the limestone surface has realistic matte texture, and the contact shadow grounds the mug firmly without floating artifacts.
Case Study 2: Narrative Portrait for an Editorial Feature
- Creative Brief: An editorial magazine portrait of an architect in her studio workspace.
Evolution 1 (Naive Prompt):
Portrait of a female architect in an office.
- Analysis: Without guidance on attire, workspace character, or lighting, this prompt leaves the mood open to chance. The risk is an uninspired corporate look with flat lighting and an indistinct background.
Evolution 2 (Adding Layers 1, 2, and 3):
Editorial magazine portrait of a woman in her late thirties wearing a dark wool sweater, seated in an architectural design studio, warm directional daylight from large industrial windows, natural skin texture.
- Analysis: Adding the subject's approximate age, clothing material, and environmental lighting immediately elevates the scene. Mentioning "natural skin texture" helps prevent the model from applying excessive plastic skin smoothing.
Evolution 3 (Full Five-Layer Production Prompt):
Editorial magazine portrait of an East Asian woman in her late thirties with a short bob haircut and a charcoal wool turtleneck sweater, seated thoughtfully beside a drafting table in an architectural design studio. Soft natural daylight from large steel-framed factory windows on the right, illuminating her profile with subtle rim lighting while leaving gentle shadows on the left. Medium portrait crop from the waist up, shallow depth of field with architectural models and tracing paper softly blurred in the background. Natural skin texture, candid thoughtful expression, no exaggerated smiling.
- What to Inspect in the Output: Check that facial skin has natural texture rather than artificial plastic smoothness, hands (if visible) have correct anatomy, and window reflections in her eyes match the direction of the studio windows.
Case Study 3: Minimal Cultural Exhibition Poster
- Creative Brief: A clean promotional poster for a contemporary ceramic and glass exhibition.
Evolution 1 (Naive Prompt):
Modern poster for a ceramic and glass art exhibition with text.
- Analysis: Asking for text without specifying exact wording and placement risks jumbled letterforms or cluttered layouts, as the model has no guidance on typography, margins, or subject arrangement.
Evolution 2 (Adding Layers and Quoting Copy):
Minimal graphic design poster for a ceramic exhibition. A sculptural white vase and a clear glass sphere arranged on a pedestal. Headline text reads "FORM & GLASS".
- Analysis: The composition becomes cleaner and quoting the exact headline gives the model specific letters to render. However, the background color, typography placement, and layout structure remain unguided.
Evolution 3 (Full Five-Layer Production Prompt):
A refined vertical gallery exhibition poster designed with a Swiss modular grid layout. At the center, an elegant still life featuring one sculptural matte white ceramic vase beside a single tinted amber glass cylinder on a pale concrete plinth. Crisp studio lighting with subtle translucent glass refractions. Clean typography with the exact headline "FORM & GLASS" set in bold capital letters across the top, and the supporting line "AUTUMN 2026" in smaller lettering below. Warm off-white background with wide, clean margins and generous negative space around the central objects.
- What to Inspect in the Output: Proofread every letter of the headline to ensure no spelling errors occurred, check that the amber glass cylinder shows convincing refraction through to the plinth, and verify that margins are balanced on both sides.
Diagnosing Common Failure Modes and Practical Fixes
Even experienced prompt writers encounter generation errors. Understanding why specific errors occur enables you to make targeted corrections rather than re-rolling prompts aimlessly.
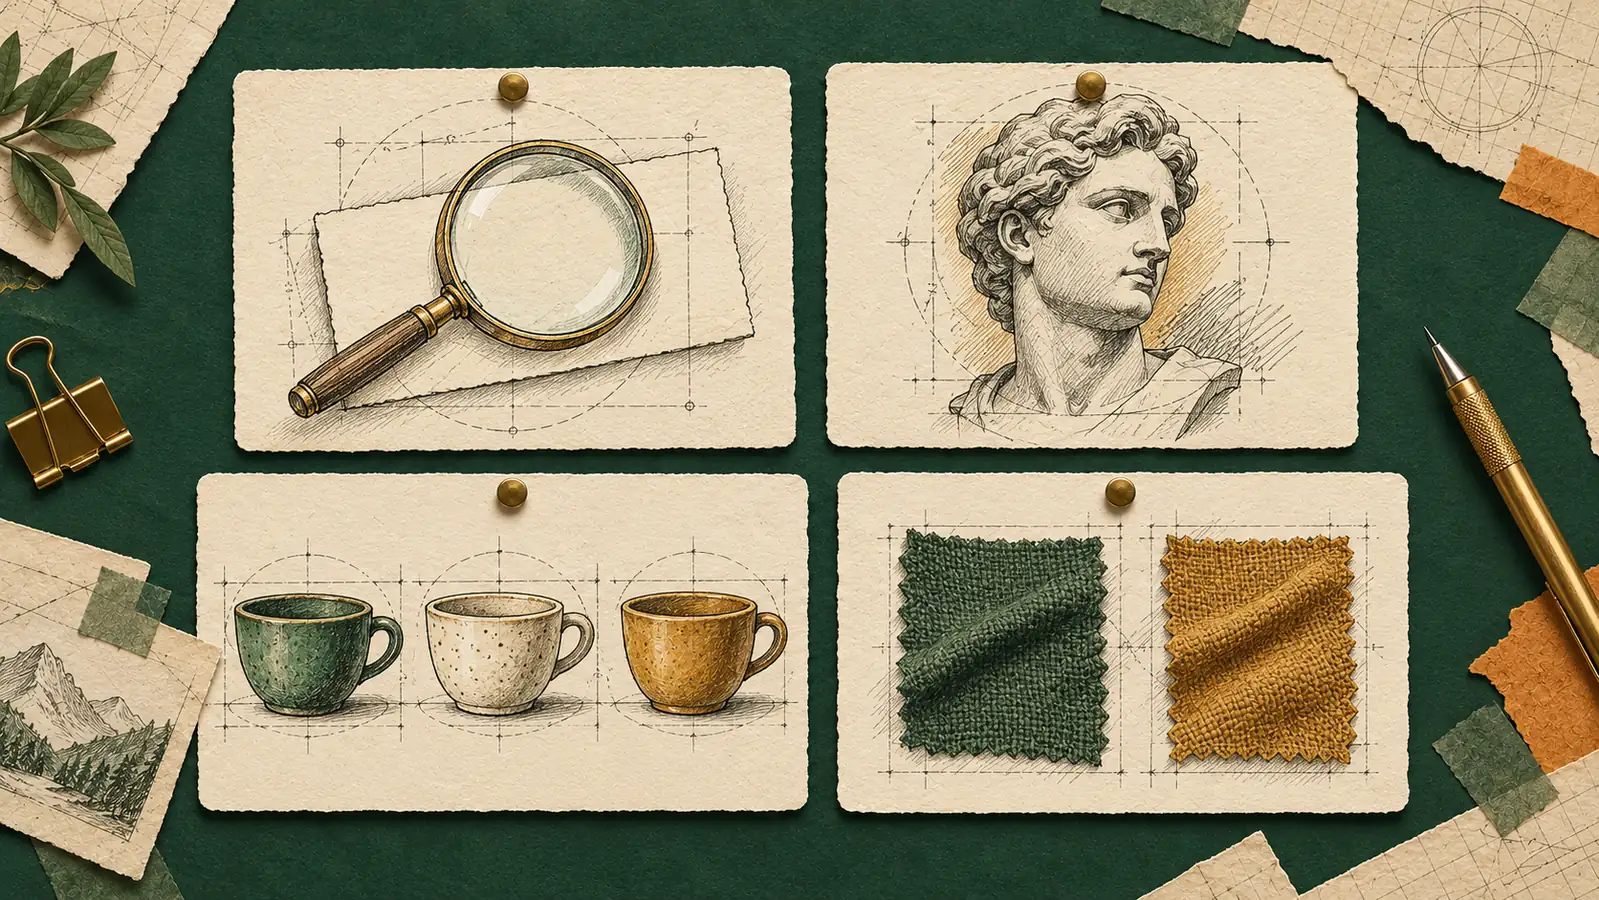
Failure Mode 1: Gibberish or Misspelled On-Image Text
- Observed Symptom: Street signs, book titles, poster headlines, or labels show garbled, pseudo-Latin letterforms, repeated characters, or nonsensical symbols.
- Why It Happens: Models treat language tokens visually. If you do not explicitly quote the exact words or if you request long sentences, the model struggles to assemble letterforms accurately.
- The Practical Fix:
- Always enclose the exact required text in double quotation marks:
headline reads "DESIGN"rather thanwith the word design. - Keep on-image text short—ideally one to three words. Long paragraphs almost always fail.
- Specify where the text belongs on the canvas:
centered headline "SUMMER SALE" along the top margin. - Test on models with established text legibility, such as Nano Banana Pro or GPT Image 2.
- Always enclose the exact required text in double quotation marks:
Failure Mode 2: Over-Smoothed, "Plastic" Skin
- Observed Symptom: Portraits look like airbrushed wax figures with waxy shine, poreless skin, and unnaturally uniform complexions.
- Why It Happens: Portraited skin may look overly smoothed when a prompt lacks descriptive surface detail or relies on generic labels that provide no concrete guidance on skin texture.
- The Practical Fix:
- Remove all generic quality descriptors from the prompt.
- Include explicit physical texture cues:
natural skin texture, subtle pores, delicate facial lines, soft unretouched daylight. - Specify natural, directional lighting (such as window light or overcast sky) rather than harsh studio flash.
Failure Mode 3: Incorrect Object Counts
- Observed Symptom: You ask for "three cups on a table" and the model renders two, four, or five cups with merged handles.
- Why It Happens: Language models often fail to bind numerical concepts strictly to visual entities when the objects are described loosely.
- The Practical Fix:
- Group the objects into a concrete spatial structure:
three ceramic cups arranged in a neat horizontal row on a wooden tray. - Differentiate the items slightly:
three cups: one cobalt blue, one cream white, and one sage green, spaced evenly. - Test on models known for literal instruction following, such as the GPT Image 2 family.
- Group the objects into a concrete spatial structure:
Failure Mode 4: Attribute Bleeding (Color and Texture Leakage)
- Observed Symptom: You ask for a person in a red jacket holding a green umbrella against a yellow wall, and you get a person in a red and green jacket with yellow umbrella stripes.
- Why It Happens: When several descriptive adjectives are placed closely together in a complex sentence, practical ambiguity arises about which adjective modifies which object.
- The Practical Fix:
- Separate subject, clothing, and background into distinct, structured clauses.
- Use explicit prepositions and spatial anchors:
A woman stands holding an umbrella. Her tailored jacket is solid red. The umbrella fabric is solid dark green. She stands before an unadorned, solid pale yellow wall.
Failure Mode 5: Conflicting Compositional Demands
- Observed Symptom: The image looks warped, with bizarre perspective vanishing points or unnatural fish-eye distortion.
- Why It Happens: Including contradictory framing terms in the same prompt—such as "close-up detail" and "wide environmental view"—forces the model to attempt an impossible perspective compromise.
- The Practical Fix:
- Pick one dominant camera distance and stick to it.
- Choose the aspect ratio (16:9, 1:1, 9:16) that naturally accommodates the framing before generating.
Practical Workflow for Multilingual Lettering
Rendering readable text in non-Latin scripts (such as Chinese characters, Japanese kanji, or Cyrillic letters) requires deliberate preparation:
- Specify Exact Script and Characters: Place the exact required characters in quotation marks within the prompt. Do not ask the model to translate concepts automatically, as models may substitute unintended idioms or incorrect characters.
- Preserve Brand Names: If your design features a brand name or proper noun, spell it out precisely in the desired script rather than relying on automatic phonetic transliteration.
- Proofread with a Literate Reader: Always zoom in to 100% and have someone familiar with that language inspect the generated character forms, radicals, and diacritics. AI models can produce letterforms that appear convincing at a glance but lack correct stroke geometry.
- Final Typesetting in Design Software: For mission-critical commercial advertising, packaging, or brand collateral, a practical best practice is generating the visual background without text on ImageGenerator.app, and performing final typographic layout in dedicated graphic design software.
Reference Tables: Audit Checklist and Anti-Patterns
Use these reference tables to review your prompts before clicking Generate and to purge ineffective buzzwords.
Pre-Submission Prompt Audit Checklist
| Layer & Inspection Point | Evaluation Question | High-Impact Phrasing Example | Common Failure Risk |
|---|---|---|---|
| Core Subject | Is the noun concrete and described by material and color? | "A sculpted terracotta vase with a wide fluted rim" | Vague nouns yield generic stock-photo aesthetics. |
| Medium & Surface | Is the artistic medium or photographic format specified? | "Editorial medium-format studio photograph" | Model defaults to ambiguous digital render styles. |
| Light & Atmosphere | Are light direction, quality, and warmth defined? | "Diffused morning daylight from the left, soft shadows" | Uncontrolled lighting creates flat, artificial contrast. |
| Framing & Angle | Are camera distance, perspective, and margins clear? | "Eye-level tabletop crop with clean top margin" | Model crops subjects tightly or clips critical edges. |
| Text & Lettering | Are all visible words short, quoted, and positioned? | 'Headline reads "ATELIER" in bold serif letters' | Unquoted text risks distorting into unreadable glyphs or spelling errors. |
| Constraints | Are boundaries clearly stated, whether framed positively or as concise limits? | "An unadorned, seamless warm-white backdrop" | Vague boundaries leave background elements or composition open to unwanted additions. |
The Anti-Pattern Matrix: Replacing Buzzwords with Descriptive Terms
| Common Descriptor | What It Leaves Unspecified | More Specific Descriptive Alternative |
|---|---|---|
| "Photorealistic" / "Hyper-realistic" | Does not describe actual materials, lighting, or camera perspective. Describe concrete textures instead. | Describe tactile surfaces: "35mm documentary photograph, natural skin pores, soft daylight falloff." |
| "8K" / "16K resolution" / "Ultra HD" | Does not alter output resolution (which is chosen in the dropdown). Describe optical sharpness if desired. | Select your desired resolution in the generator, and describe optical sharpness: "sharp focus on central subject." |
| "Trending on ArtStation" | Does not specify medium, palette, or technique. Name the actual artistic medium or color palette. | Name the specific medium and style: "matte gouache illustration with a muted earth-tone palette." |
| "Masterpiece" / "Award-winning" | Does not state an observable requirement. State the specific composition, lighting, and materials instead. | State the specific composition, lighting direction, and materials you want to see. |
| "No blur, no watermarks" | Valid negative constraint. Pairing negative constraints with positive descriptions can help clarify scene requirements. | Combine concise exclusions with positive descriptions: "crisp focus throughout, clean unmarked backdrop." |
Model-Specific Prompting Nuances: Testing Starting Hypotheses
On ImageGenerator.app, switching between foundation models is as simple as selecting an option from the model dropdown. Each model family reflects distinct training emphases and alignment behaviors. Treat these family characteristics as starting hypotheses to test against your creative brief rather than universal guarantees:
The OpenAI GPT Image Family
- Key Candidates: GPT Image 2, GPT Image 2.5 Flare, and GPT Image 2.5 Sunburst.
- Credit Rate: All three models share the same rate of 16 credits at 1K, 31 credits at 2K, and 52 credits at 4K resolution.
- Suggested Use: Best suited when your brief contains strict spatial instructions, numbered items, diagrammatic layouts, or quoted headlines. Structuring your prompt as a short, organized list of clauses often yields exceptionally literal adherence on these models.
The Google DeepMind Gemini Image Family (Nano Banana)
- Key Candidates: Nano Banana 2.1 (10 credits at 1K), Nano Banana 2 (20 credits at 1K), and Nano Banana Pro (39 credits at 1K).
- Suggested Use: Strong candidates when your scene involves complex spatial interactions between multiple subjects, crowded streetscapes, or intricate on-image typography. When using Nano Banana Pro for signage or posters, keep quoted text prominent and specify font styles clearly.
The ByteDance Seedream Family
- Key Candidates: Seedream 5.0 Flash (9 credits across 1K/1.5K/2K), Seedream 4.0 (12 credits across 1K/2K/4K), and Seedream 5.0 Pro (18 credits at 1K, 35 credits at 2K).
- Suggested Use: Excellent candidates for rich painterly illustration, cinematic character art, vibrant color palettes, and posters featuring East Asian or multilingual cultural lettering. Seedream models respond well to mood descriptors, atmospheric lighting, and tactile surface descriptions.
Testing Discipline: Workspace History and Local Version Logging
The key to mastering image prompting is systematic iteration. Changing five variables between runs makes it impossible to know which word caused the improvement or breakdown.
The One-Variable Testing Strategy
When refining an image that is approaching your creative goal:
- Hold baseline parameters stable: Keep the selected model, resolution, aspect ratio, and any uploaded reference images constant.
- Change one prompt clause: Alter only the lighting description, or adjust the medium phrasing, or modify the framing angle.
- Acknowledge inherent randomness: Because standard image generation is variable and does not offer fixed seed controls, changing a single clause will not provide strict laboratory A/B certainty. Generate and compare two or three runs if necessary to assess whether the wording change consistently moves the image in your desired direction.
Practical Workspace Workflow
ImageGenerator.app provides several tools to facilitate prompt experimentation without requiring manual re-typing:
- Explore Tested Prompts: Visit the
/promptslibrary to review a directory of sample images paired with the exact prompts and models used to generate them. Clicking any sample loads its text directly into the generator. - Review Recent Creations: The workspace keeps your recent generations accessible in your active session. You can copy prompts from prior runs with a single click, compare variations side by side, and download high-resolution files.
- Manual Re-Upload for Reference: When you produce a promising candidate that needs further refinement, download the image and upload it into the reference strip for an image-to-image pass. The platform does not claim automatic versioning; maintaining a simple local log provides the most reliable project archive.
Keeping a Local Testing Log
While ImageGenerator.app maintains your recent creations history in your session, keeping a simple local notes file ensures you never lose a winning prompt combination:
- Date & Run Number: Record the sequence of your creative sprint.
- Model & Resolution: E.g.,
GPT Image 2 @ 1KorSeedream 5.0 Pro @ 2K. - Prompt Text: Save the exact prompt string used.
- Observed Flaw: E.g., "Mug handle warped," "Lighting too flat," or "Text spelled correctly."
- Next Prompt Action: E.g., "Add side daylight clause" or "Quotation marks around headline."
This structured record allows you to trace your steps backward if a prompt revision leads into a creative dead end.
Responsible Prompting and Community Guidelines
Visual AI tools should be used thoughtfully and responsibly. Observe these standard operational boundaries when composing prompts:
- Third-Party Service Notice: ImageGenerator.app is an independent web application. It is not an official application of Google DeepMind, ByteDance, OpenAI, or any other foundation model developer. Model weights and architectures are researched and operated by their respective labs.
- Respect Likeness and Privacy: Do not use prompts designed to generate deceptive deepfakes, non-consensual depictions of private individuals, or defamatory content.
- Intellectual Property: Avoid attempting to produce deceptive commercial counterfeits of trademarked goods or protected branding.
- Commercial Verification: Always verify that your commercial use complies with platform guidelines and applicable model provider terms. Consult our Terms of Service for acceptable use rules.
- Billing and Task Disconnections: Failed generations caused by upstream errors are not charged to your account. If your internet connection drops while an image is rendering, check your session history before re-submitting to ensure you do not initiate redundant tasks.
Frequently Asked Questions (FAQ)
How long should an image prompt be?
There is no universal word count rule. An effective prompt is concise enough to keep your creative requirements coherent while providing clear visual guidance across subject, medium, lighting, and framing. In our catalog, two specific models enforce explicit prompt character boundaries: the original Nano Banana and Seedream 4.0 both have a documented maximum prompt length of 1,000 characters. For other models where specific limits are not published, writing focused, descriptive sentences without repetitive filler remains the most effective practice.
Should I use negative prompts or positive constraints?
Concise negative constraints included directly within your main prompt can be helpful for establishing clear boundaries. At the same time, clear positive descriptions that specify the intended environment and surfaces often provide more effective visual direction. ImageGenerator.app does not provide a dedicated negative-prompt field, so test both concise exclusions and detailed positive scene descriptions on your selected model to see which produces better results for your specific brief.
Do quotes around text guarantee that the model will spell words correctly?
Quotation marks provide a strong signal that the enclosed characters should be rendered literally, but they do not provide an absolute technical guarantee. Always inspect the generated text at 100% zoom. If a letter is missing or malformed, re-roll the prompt or test a model with proven text rendering like Nano Banana Pro.
Does generating at 2K or 4K resolution make the prompt work better?
Higher resolutions provide sharper pixel detail, finer micro-textures, and crisper contours, but they do not resolve fundamental composition or lighting ambiguities in your prompt. It is usually best to test your prompt phrasing at the lowest supported resolution available for your chosen model (noting that while many models offer 1K options, certain catalog models like Seedream 5.0 Lite and Seedream 4.5 begin natively at 2K). Once the composition meets your expectations, you can escalate to higher resolutions for final production assets.
Why does the same prompt produce different images each time I click Generate?
Generative image models are inherently variable. A written prompt and a model selection establish broad visual boundaries, but they do not specify every single pixel on the canvas. Because models sample possible interpretations each time you run a job, you should expect natural variation rather than exact pixel repeatability.
Can I copy prompts from other artists and expect the same results?
A prompt copied from another platform or model will often look very different on ImageGenerator.app because different model families have distinct aesthetic distributions and text encoders. Use copied prompts as structural templates, but adapt the visual vocabulary to your chosen foundation engine.
Conclusion: Crafting Prompts as Professional Briefs
Prompt engineering is not about finding mystical keywords or secret formulas. It is about communicating visual intent clearly, structured in layers the model can systematically execute:
- Anchor the subject with concrete nouns, specific colors, and defined materials.
- State the medium explicitly to avoid generic digital-render defaults.
- Dictate lighting direction, warmth, and quality to establish depth and contrast.
- Establish framing and camera perspective to ensure balanced composition.
- Apply positive constraints and audit the output against common failure modes.
To practice prompt layering and evaluate different model interpretations in real time, open the text-to-image workspace, check available resolution pricing on our Pricing Page, browse model specifications in the Models Directory, and read our guides on the Best Multi-Model AI Image Generator in 2026 and Browser Access to Foundation Models.